







Microsoft has identified the underlying causes of the global outage that disrupted Outlook, Exchange and several other essential office software services last week.
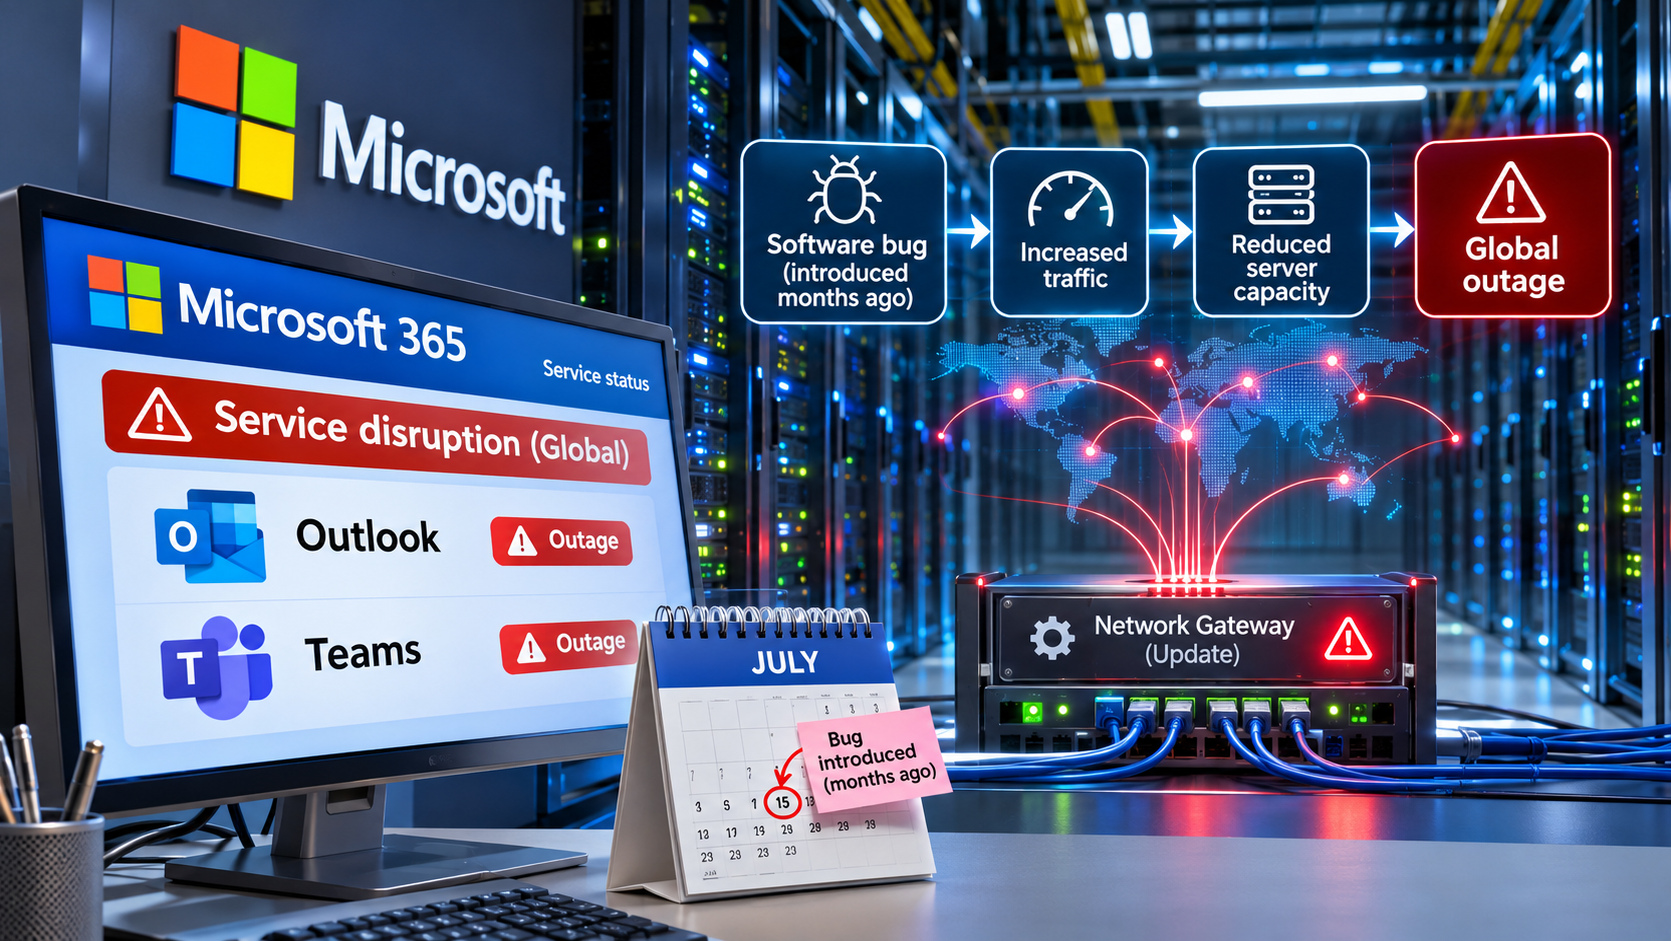
In an initial report published on Monday, the technology company identified three contributing factors behind the 24-hour service disruption: a software bug that had existed for several months, problems with internal network connections and reduced server capacity. Microsoft executives explained that each issue could potentially have been resolved independently, but their combined impact resulted in a major outage that proved more difficult to contain.
The disruption began on Thursday, when users in the US reported problems accessing their Outlook email accounts. As the incident continued into Friday, millions of people across the world found themselves unable to access their emails and other Office 365 services.
The outage had serious consequences for essential services. Prisons were unable to release inmates, hospitals resorted to paper-based records, schools lost communication with parents, and police departments experienced difficulties receiving crime reports. Microsoft said the problem had been resolved and services restored by Saturday, while also issuing an apology. The company did not link the incident to a cybersecurity breach.
In a post on X on Monday, Charles Lamanna, Microsoft’s executive vice-president of Copilot, Agents and Platform, explained that a previously undetected bug dating back to July caused the company’s servers to “become overwhelmed and unresponsive”.
Lamanna said Microsoft normally operates two networking gateways, which act as entry and exit points connecting different systems and enabling data transfers. However, one of these gateways was not functioning correctly for Microsoft Teams, placing excessive pressure on the primary gateway. At the same time, an unrelated problem from the previous day had left more than 14% of the company’s server capacity unavailable.
“Taken together, the increased load and the reduced server capacity, caused the network gateway to encounter the latent bug from July,” Lamanna wrote. “This caused requests to build up until servers ultimately stopped responding. This occurred during the peak window of traffic in the United States.”
Microsoft also faced difficulties resolving the underlying software defect because it had originated several months earlier. As a result, reversing a recent software update would not have been sufficient to eliminate the problem, Lamanna said.
“Recovery took longer than usual because as servers returned to service, they were immediately overwhelmed by waiting traffic and became unresponsive again,” he wrote. “Our normally automated recovery processes were not designed to restore service from this broad unresponsive state. Additionally, since the main code defect was a latent bug from several months previous, our normal rollback, flighting, and feature flags were unable to quickly revert the change.”
Lamanna added that Microsoft intends to release a final report containing further details about the incident.
Industry analysts said the widespread disruption highlights the importance of businesses reviewing their dependence on a single operating system and ensuring they have effective contingency arrangements.
“This is a prime example of the importance of not only cyber resilience, but business resilience,” said Matt Hull, vice-president of cyber intelligence and response at NCC Group. “Reports that hospitals, schools and other essential services are affected demonstrate the wide impact that a system outage can have, regardless of the cause.”